orgami org + origami — folding a flat sheet of repositories into a shape you can see.
Ten repos, eight people, and nobody whose job it is to write the docs. orgami maps every repository in your GitHub organization — what each one is, how to run it, what it talks to, where it deploys — digests what the team shipped today and this week, keeps the things you only learn once, and hands all of it to your coding agent at session start.
vhs docs/demo.tape —
every line in it came out of a committed file.What it is for
The size of team where everyone touches everything: no architect holding the diagram, no wiki that survived the last three months, and a new hire or a coding agent expected to be useful on day one.
A map you can check
Every edge carries the file:line it came from, so nothing in it is a
model's guess. A missing edge means “not found in committed configuration”, never
“not connected”.
Digests you can trust the numbers in
jq computes every figure; Claude only writes the prose, and is told the
numbers rather than asked to count.
One memory for the team
The cause someone found at 2am gets written down once — often without anyone typing it — and everyone's agent reads it.
Nothing to run
Open Claude Code or Cursor in a mapped checkout and the repo's stack, commands, linked repos and notes are already in the session.
Install
One command. It installs what is missing, puts orgami on your PATH, and
wires up Claude Code and Cursor if they are on the machine.
curl -fsSL https://raw.githubusercontent.com/achevalier-dev/orgami/main/bootstrap.sh | bashWindows, in PowerShell:
irm https://raw.githubusercontent.com/achevalier-dev/orgami/main/bootstrap.ps1 | iexThen, once, on one machine:
gh auth login
orgami init     # map your organization
Everyone else on the team runs orgami join and picks it up — no scan, no
clones. --dry-run prints every step without touching anything;
installing by
hand is documented too.
The map
orgami scan shallow-clones every non-archived, non-fork repo in the
organization and pattern-matches what is committed — deploy tooling, servers, backing
services, repo-to-repo references, frameworks, run and test commands, routes, shared
environment contracts. The result is map/graph.json; the architecture
document, the mermaid diagrams and the terminal view all render from it.
orgami view              # the map, the repos, the notes and the recaps, in one screen
orgami query thruster    # one node and its edges, as text
orgami html              # the same graph, force-directed, in one openable file
Every edge says whether it is extracted — a literal string in a committed file,
with the file:line you can open — or inferred, resolved by matching
one repo's reading against another's. Both are worth having; only one can be checked, and
a map that does not draw that line is quietly lying about the difference.
map/graph.html is the map as a picture: filterable, clickable down to the
evidence, and self-contained — no CDN, no network — so it opens from a file://
URL and inside a private repository.
Beside it sit the organization's gathered conventions, decisions mined from merged pull requests, runbooks per repo, and which repos keep changing together.
Which repo defines this
The scan is pattern-matching, which is what keeps it cheap enough to run over forty
repositories. It also cannot tell you where chargeCustomer lives.
orgami depth parses instead — every file through a tree-sitter grammar, so a
definition is a definition node and the line is the parser's, not grep's.
orgami depth                          # 6,600 files in about two seconds
orgami depth --symbol chargeCustomer  # which repo defines it, and where
It is the one part of orgami that needs more than Bash, gh and
jq, so it installs its grammars into a virtualenv of its own, stays out of the
weekly run, and the map is complete without it.
The digests
A day is not a week in miniature: most of a day's work has not merged yet. So
orgami daily reads what merged, what opened, what is sitting open with nobody
on it, and commits that never became a pull request at all — the half a merge-based recap
cannot see. A quiet day produces no file.
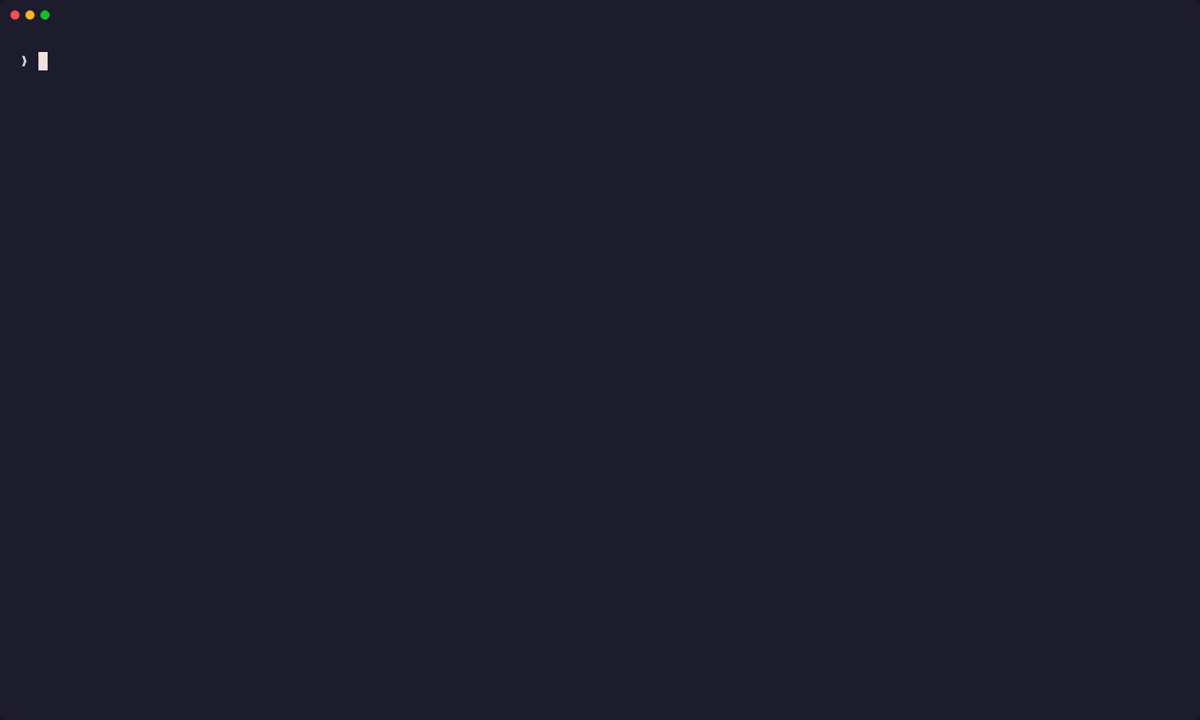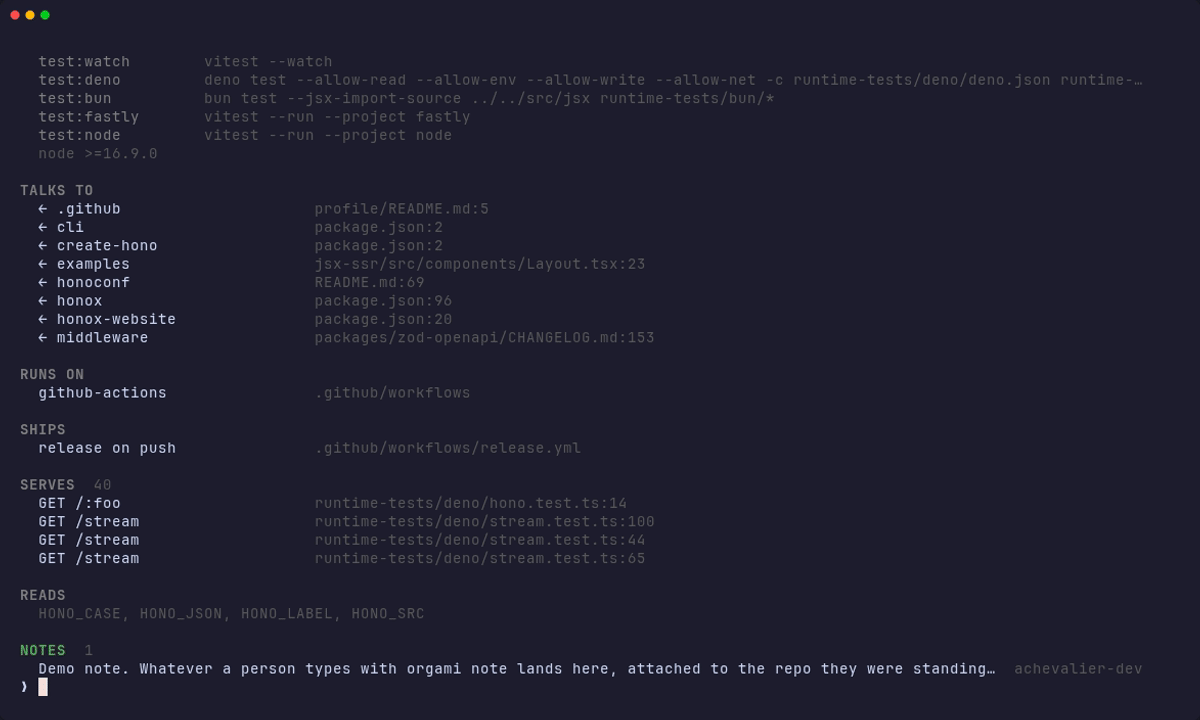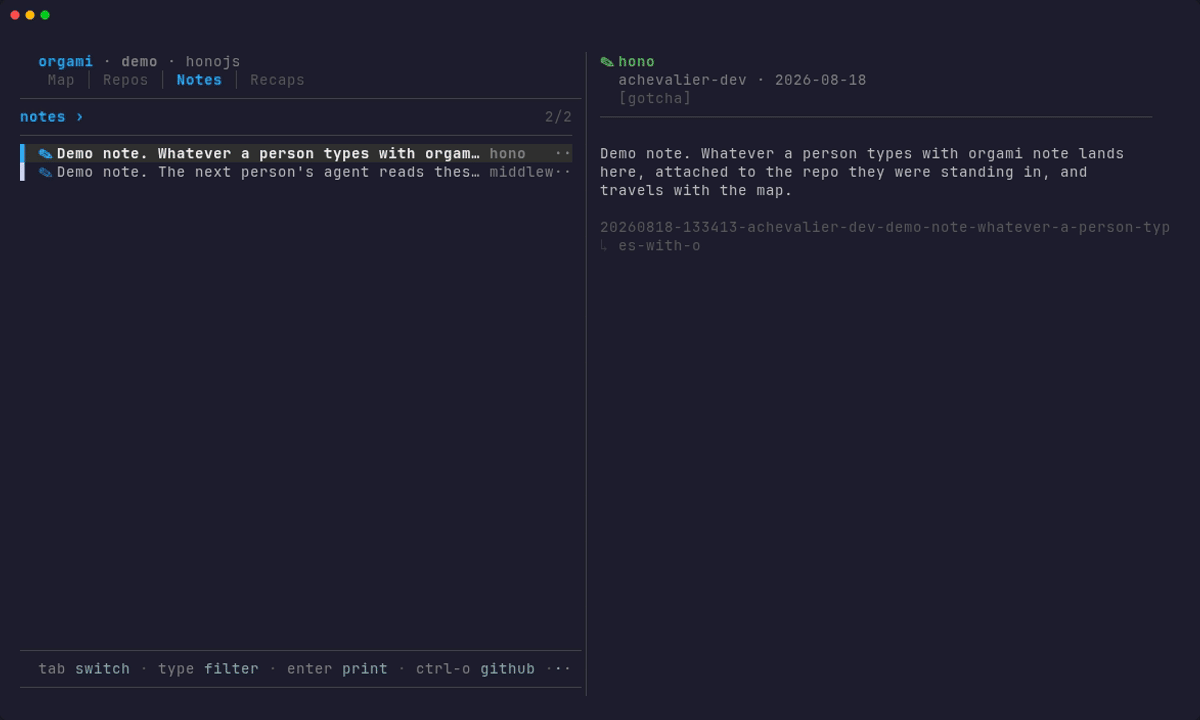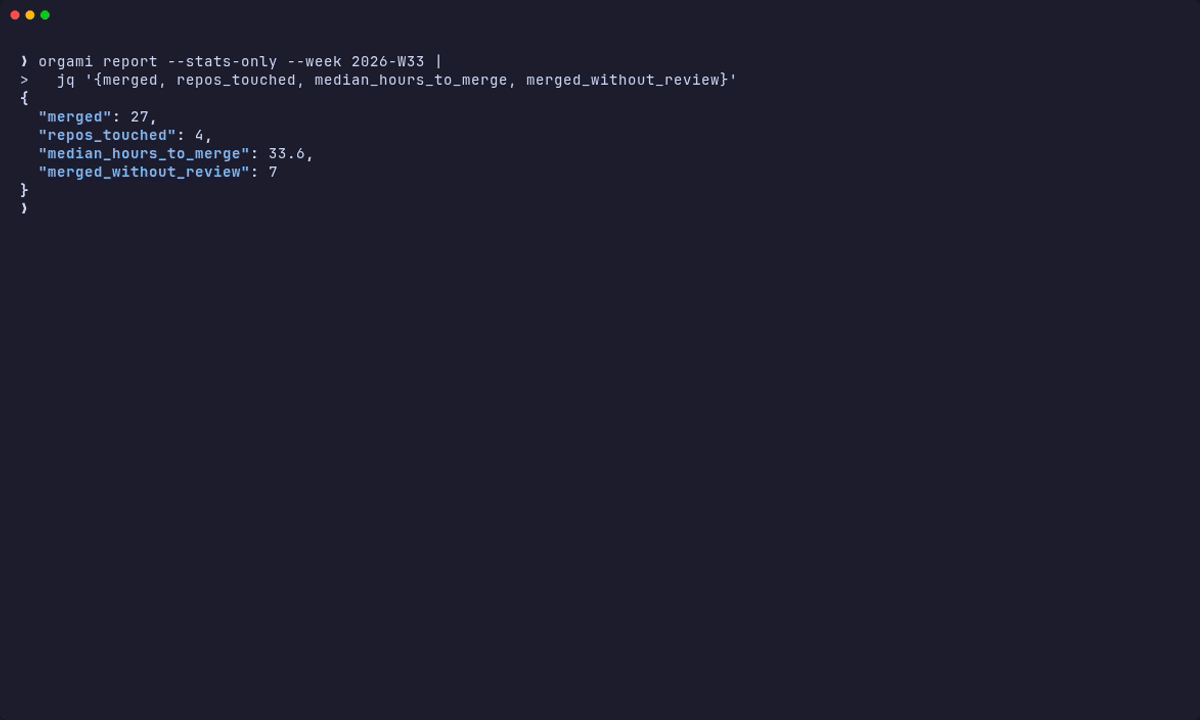
orgami daily --stats-only     # the numbers, no model call, no cost
orgami report                 # the week, written from the same statistics
A model asked to both count and narrate will do neither reliably, and a digest nobody trusts the numbers in is not worth writing.
Cost
Two Claude calls a week — the recap and the decision mining — plus one short one per
weekday morning if the daily digest is on. Everything else is gh,
git, jq and grep, and every
--stats-only run costs nothing at all. No daemon, no database, no web app:
Bash, a timer, and plain files that diff cleanly in git.